Data Engineer Resume 2026: How to Write a Resume That Lands Data Engineering Jobs

Why a dedicated data engineer resume matters in 2026
Data engineering is one of the fastest-moving roles in tech, and your resume has to prove two things at once: that you can build and maintain reliable pipelines, and that you can do it with a modern stack. A generic “engineer” resume won’t cut it — recruiters and the AI systems that screen your application both look for concrete pipeline language, real tooling, and measurable impact.
The bar has shifted. It is no longer enough to say you “worked with data.” In 2026 the strongest data engineer resumes read like a field report from a production system: they name the stack, they quantify throughput and latency, and they tie every technical decision to a business outcome. That’s exactly what we’ll build here — a step-by-step, ATS-safe, recruiter-proof resume that gets you past the filter and into the interview.
The exact data engineer resume format that works
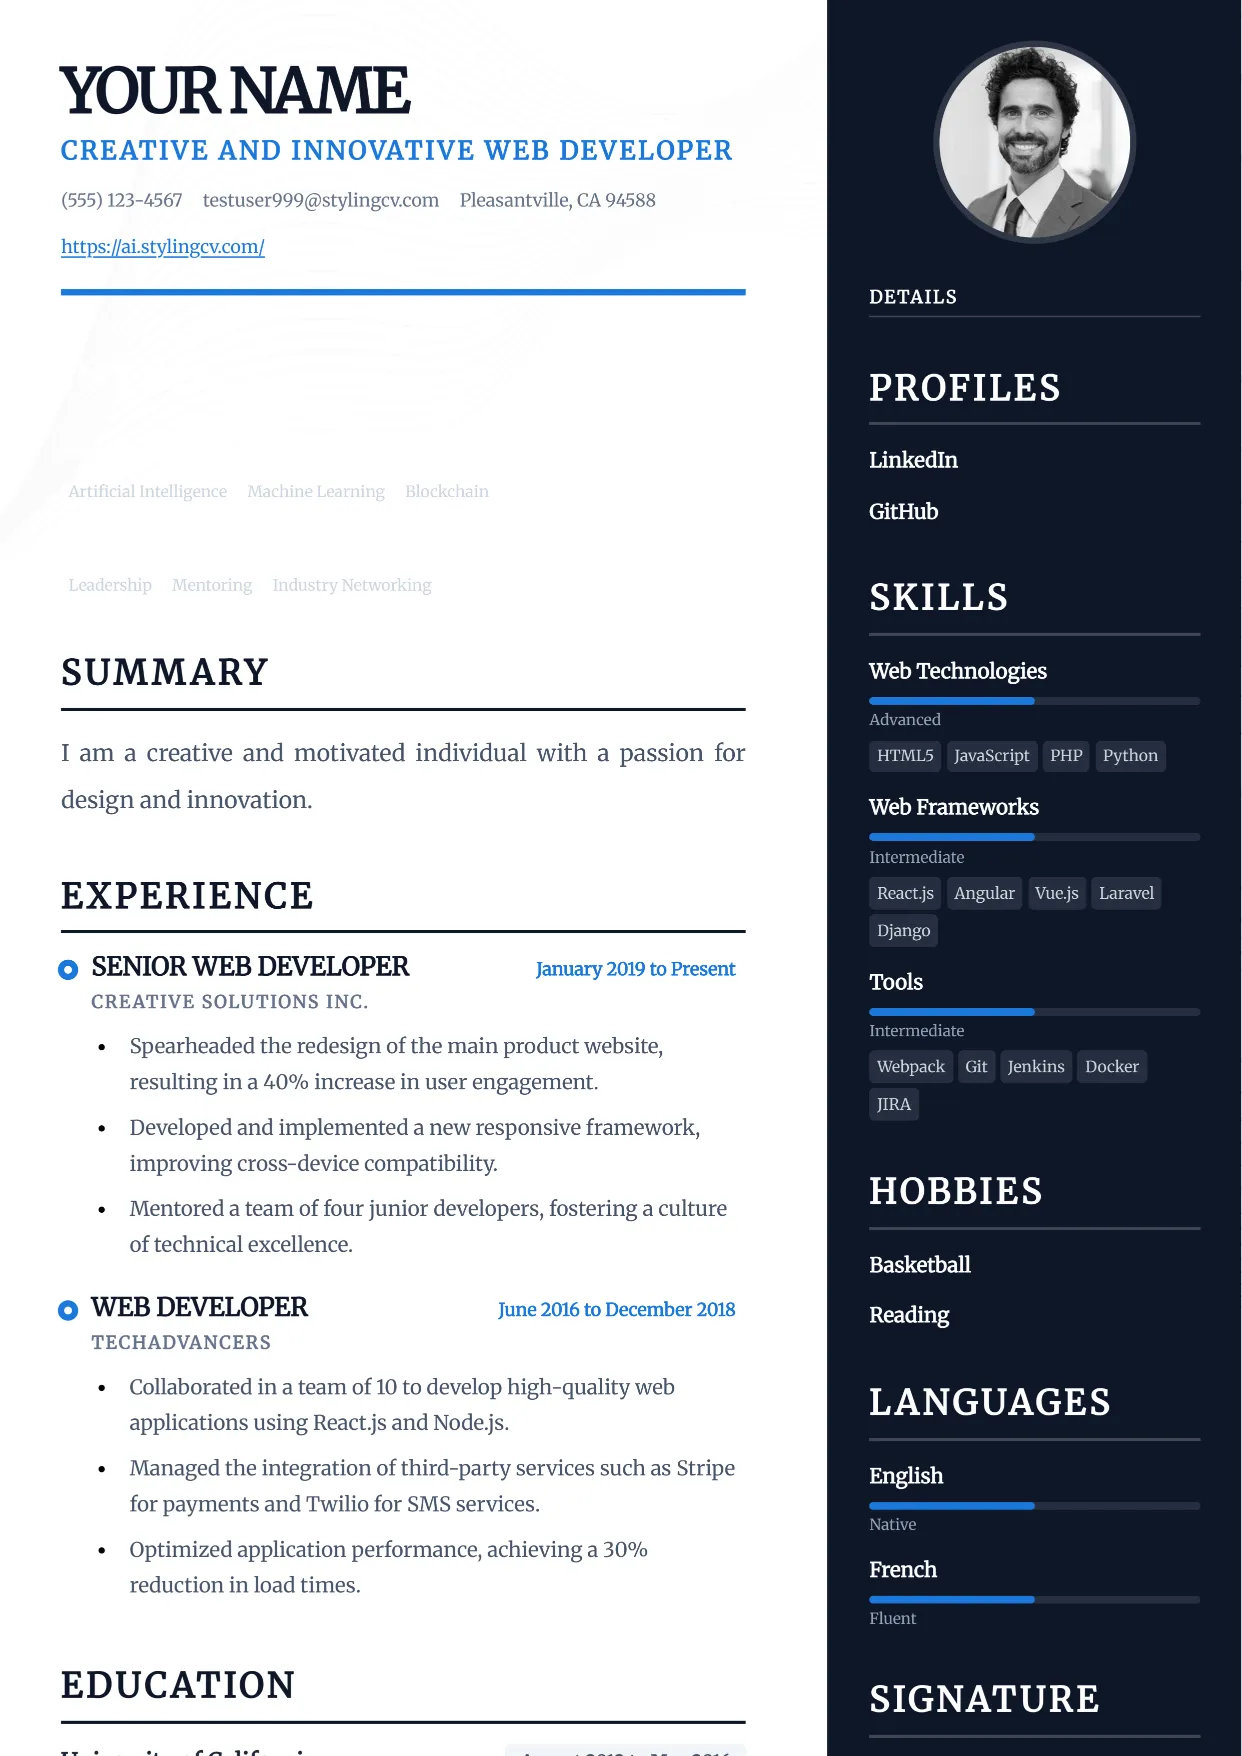
Follow this section order. It is optimised for both human skimming and parsing software, and it works whether you’re a seasoned staff engineer or breaking in from analytics:
- Header — name, title, location, phone, email, GitHub, LinkedIn. Nothing else.
- Professional Summary — 2 to 3 lines: years of experience, primary stack, top achievement, target role.
- Core Skills — grouped clusters of tools and languages, each with a keyword-rich label.
- Experience — reverse-chronological, with quantified bullet points.
- Projects — 1 to 3 real pipelines with links to repos and observability dashboards.
- Certifications & Education — cloud certs (AWS/Azure/GCP), dbt, Airflow, and your degree.
One page for less than 10 years of experience, two pages max for senior roles. Brevity is a signal of clarity.
How to write a data engineer resume in 2026: step by step
Step 1 — Write a summary that names your stack and your impact
Your first three lines decide whether anyone reads further. Avoid “passionate data professional.” Use the pattern: role + years + stack + one quantified outcome.
Example: “Data engineer with 5 years building production-grade ETL pipelines in Python and Apache Airflow on AWS. Reduced data load times by 40% and automated 30+ recurring reporting workflows, serving analytics for a 2M-user platform. Experienced with dbt, Snowflake, and Kubernetes.”
Step 2 — Group your skills into scannable clusters
Don’t dump one long comma list. Clusters make you readable to humans and keyword-matchable to ATS. Example groups:
- Languages: Python, SQL, Java, Bash
- Orchestration & Transformation: Apache Airflow, Prefect, dbt, Dagster
- Data Stores: PostgreSQL, Snowflake, BigQuery, Redshift, MongoDB
- Streaming & Big Data: Apache Spark, Kafka, Flink
- Infrastructure & DevOps: Docker, Kubernetes, Terraform, CI/CD, Git
- Cloud & Monitoring: AWS, GCP, Azure, Datadog, Grafana
Step 3 — Quantify every bullet in Experience
Data engineers move data, so metrics are your native language. For each role, write bullets that answer: how much data, how fast, how reliably, and at what cost?
- Designed and maintained ETL pipelines processing 10M+ daily events with 99.9% success rate.
- Cut pipeline runtime from 6 hours to 90 minutes by refactoring Airflow DAGs and indexing warehouse tables.
- Automated schema change detection, reducing data-quality incidents by 60%.
- Migrated legacy batch jobs to cloud, saving $12K/month in infrastructure costs.
If you lack hard metrics from an employer, estimate conservatively and be ready to explain your reasoning — interviewers respect a well-reasoned estimate.
Step 4 — Add projects that prove you can ship
A public repo of a working end-to-end pipeline is worth more than a dozen buzzwords. Show the whole chain: ingestion → transformation → load → observability. For each project, note the stack and the problem it solved.
Example: “Real-time clickstream pipeline: Kafka → Spark → Snowflake, orchestrated with Airflow, monitored in Grafana. Processes 5M events/hour with sub-minute latency.”
Step 5 — List certifications that match the role
Cloud and tool certifications still move the needle for screening. Include AWS Certified Data Engineer, GCP Professional Data Engineer, dbt, and Airflow credentials if you hold them, and only list certs you can defend in an interview.
Data engineer resume sample (ATS-friendly)
| Section | What to write |
|---|---|
| Summary | Data engineer, 5 yrs, Python + Airflow + AWS, cut load times 40% |
| Skills | Clusters: languages, orchestration, data stores, streaming, infra, cloud |
| Experience | Reverse-chronological, 3 quantified bullets per role |
| Projects | 2 public repos with stack + outcome |
| Education/Certs | Degree, AWS/GCP/dbt certifications |
Common data engineer resume mistakes to avoid
- Using vague tools instead of the real stack. Say “Apache Airflow,” not “ETL tools.”
- No numbers. “Built pipelines” is a claim; “built 40 pipelines serving 12 teams” is evidence.
- Missing the ATS. Columns, images, and fancy fonts break parsing and quietly remove your application.
- Ignoring the job description keywords. Screeners match exact phrases — mirror the JD’s terminology.
- Underselling infrastructure work. Docker, Kubernetes, and Terraform are differentiators — put them front and center.
How StylingCV helps you build this resume fast
You don’t need to start from a blank page. StylingCV’s AI resume builder uses 11 specialised agents to turn your raw experience into a polished, ATS-safe data engineer resume with role-specific phrasing and impact metrics — in minutes, not hours. Pick one of our professionally designed resume templates, or generate a complete CV and pair it with a compelling cover letter.
Ready to land your next data engineering role? Write your resume with StylingCV’s AI and see how a clear, keyword-rich, outcome-driven resume changes the response rate on your applications.
Frequently asked questions about data engineer resumes
Should a data engineer resume be one page or two?
One page for fewer than 10 years of experience, up to two for senior or staff roles. Either way, cut ruthlessly — every line should earn its place.
Do I need a portfolio or projects section if I have work experience?
Yes, especially if you’re early-career or pivoting. Public, reproducible pipeline projects are one of the strongest signals that you can do the job, and they give interviewers a natural conversation starter.
What’s the most important section on a data engineer resume?
The experience section, written with quantified impact. It’s where hiring managers and ATS systems spend the most weight — solid metrics here carry the whole document.
Can I apply for data engineering roles without a computer science degree?
Absolutely. Practical skills, projects, and cloud certifications regularly outweigh formal degrees in this field. Focus your resume on demonstrable pipeline work and measurable outcomes rather than credentials.